Bookmarks
RSS feed
Loading...
🎧 Concentration10 bookmarks🔖 Good Reads40 bookmarks🧑‍🚒 Engineering13 bookmarks🦾 Artificial Intelligence41 bookmarks👓 UX & Frontend78 bookmarks🧈 Code Quality12 bookmarks🧪 Testing5 bookmarks📱 Mobile3 bookmarks💳 Online Payments & Billing6 bookmarks🔍 SEO Tools / Marketing5 bookmarks💹 Trading3 bookmarks🌼 Great Designs26 bookmarks💉 Security12 bookmarks
Loading...
🔖 Good Reads
Loading...

🔖 Good Reads

Loading...
Dario Amodei — The Urgency of Interpretability

Dario Amodei — The Urgency of Interpretability

darioamodei.com
Home - Keep The Future Human

Home - Keep The Future Human

keepthefuturehuman.aiHumanity is on the brink of developing artificial general intelligence that exceeds our own. It's time to close the gates on AGI and superintelligence... before we lose control of our future.
Gradual Disempowerment

Gradual Disempowerment

gradual-disempowerment.ai
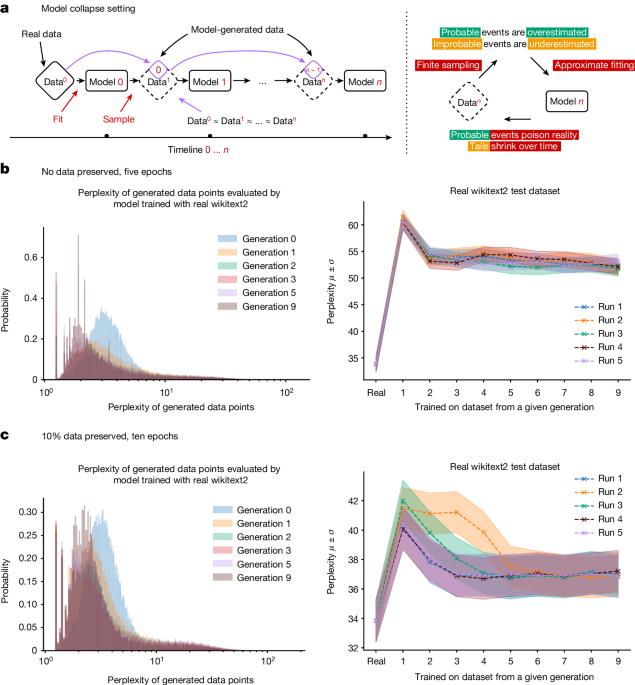
AI models collapse when trained on recursively generated data - Nature

AI models collapse when trained on recursively generated data - Nature

nature.com Analysis shows that indiscriminately training generative artificial intelligence on real and generated content, usually done by scraping data from the Internet, can lead to a collapse in the ability of the models to generate diverse high-quality output.
AIs have a favorite number, and it's not 42

AIs have a favorite number, and it's not 42

theregister.com: Ask a model to guess a number from 1 to 50 and it's likely to answer 27
ChatGPT Is a Blurry JPEG of the Web

ChatGPT Is a Blurry JPEG of the Web

newyorker.comOpenAI’s chatbot offers paraphrases, whereas Google offers quotes. Which do we prefer?
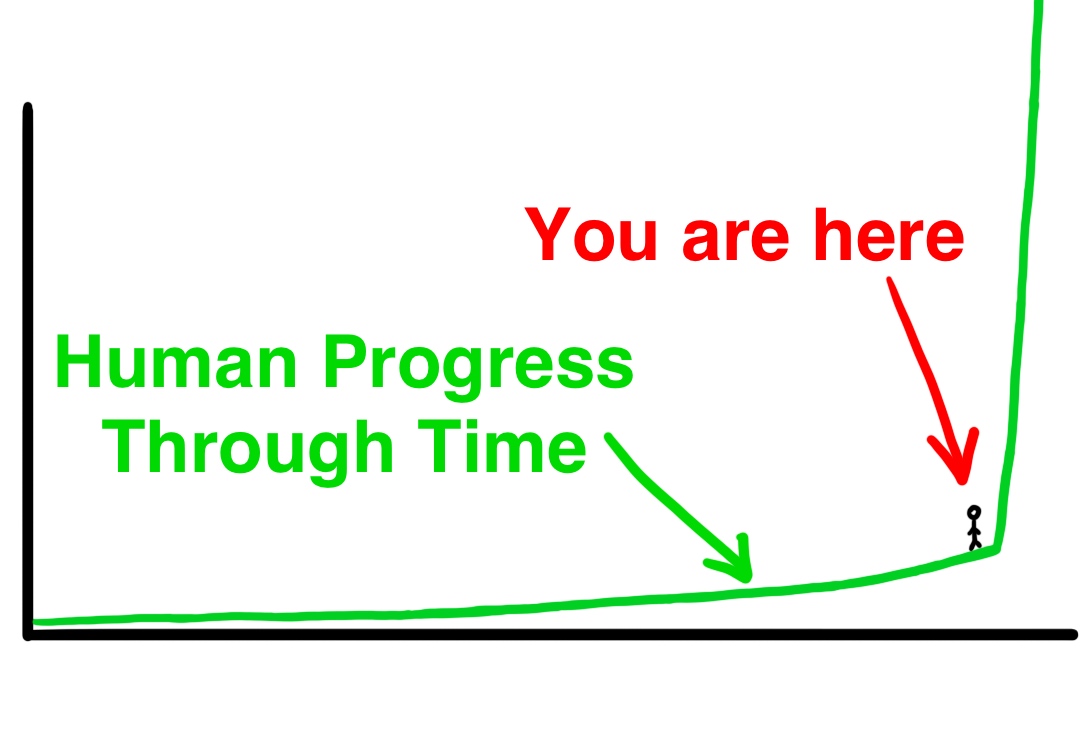
The AI Revolution: The Road to Superintelligence

The AI Revolution: The Road to Superintelligence

waitbutwhy.comPart 1 of 2: "The Road to Superintelligence". Artificial Intelligence — the topic everyone in the world should be talking about.
What Is ChatGPT Doing … and Why Does It Work?

What Is ChatGPT Doing … and Why Does It Work?

writings.stephenwolfram.comStephen Wolfram explores the broader picture of what's going on inside ChatGPT and why it produces meaningful text. Discusses models, training neural nets, embeddings, tokens, transformers, language syntax.
The Scaling Hypothesis

The Scaling Hypothesis

gwern.netOn GPT-3: meta-learning, scaling, implications, and deep theory. The scaling hypothesis: neural nets absorb data & compute, generalizing and becoming more Bayesian as problems get harder, manifesting new abilities even at trivial-by-global-standards-scale. The deep learning revolution has begun as foretold.
On Chomsky and the Two Cultures of Statistical Learning

On Chomsky and the Two Cultures of Statistical Learning

norvig.com
Man-Computer Symbiosis

Man-Computer Symbiosis

groups.csail.mit.edu
As We May Think

As We May Think

theatlantic.com“Consider a future device ... in which an individual stores all his books, records, and communications, and which is mechanized so that it may be consulted with exceeding speed and flexibility. It is an enlarged intimate supplement to his memory.”
I.—COMPUTING MACHINERY AND INTELLIGENCE

I.—COMPUTING MACHINERY AND INTELLIGENCE

academic.oup.comI propose to consider the question, ‘Can machines think?’ This should begin with definitions of the meaning of the terms ‘machine’ and ‘think’. The definit
Neural networks and deep learning

Neural networks and deep learning

neuralnetworksanddeeplearning.com
The Illustrated Transformer

The Illustrated Transformer

jalammar.github.ioDiscussions: Hacker News (65 points, 4 comments), Reddit r/MachineLearning (29 points, 3 comments) Translations: Arabic, Chinese (Simplified) 1, Chinese (Simplified) 2, French 1, French 2, Italian, Japanese, Korean, Persian, Russian, Spanish 1, Spanish 2, Vietnamese Watch: MIT’s Deep Learning State of the Art lecture referencing this post Featured in courses at Stanford, Harvard, MIT, Princeton, CMU and others Update: This post has now become a book! Check out LLM-book.com which contains (Chapter 3) an updated and expanded version of this post speaking about the latest Transformer models and how they've evolved in the seven years since the original Transformer (like Multi-Query Attention and RoPE Positional embeddings). In the previous post, we looked at Attention – a ubiquitous method in modern deep learning models. Attention is a concept that helped improve the performance of neural machine translation applications. In this post, we will look at The Transformer – a model that uses attention to boost the speed with which these models can be trained. The Transformer outperforms the Google Neural Machine Translation model in specific tasks. The biggest benefit, however, comes from how The Transformer lends itself to parallelization. It is in fact Google Cloud’s recommendation to use The Transformer as a reference model to use their Cloud TPU offering. So let’s try to break the model apart and look at how it functions. The Transformer was proposed in the paper Attention is All You Need. A TensorFlow implementation of it is available as a part of the Tensor2Tensor package. Harvard’s NLP group created a guide annotating the paper with PyTorch implementation. In this post, we will attempt to oversimplify things a bit and introduce the concepts one by one to hopefully make it easier to understand to people without in-depth knowledge of the subject matter. 2025 Update: We’ve built a free short course that brings the contents of this post up-to-date with animations: A High-Level Look Let’s begin by looking at the model as a single black box. In a machine translation application, it would take a sentence in one language, and output its translation in another.
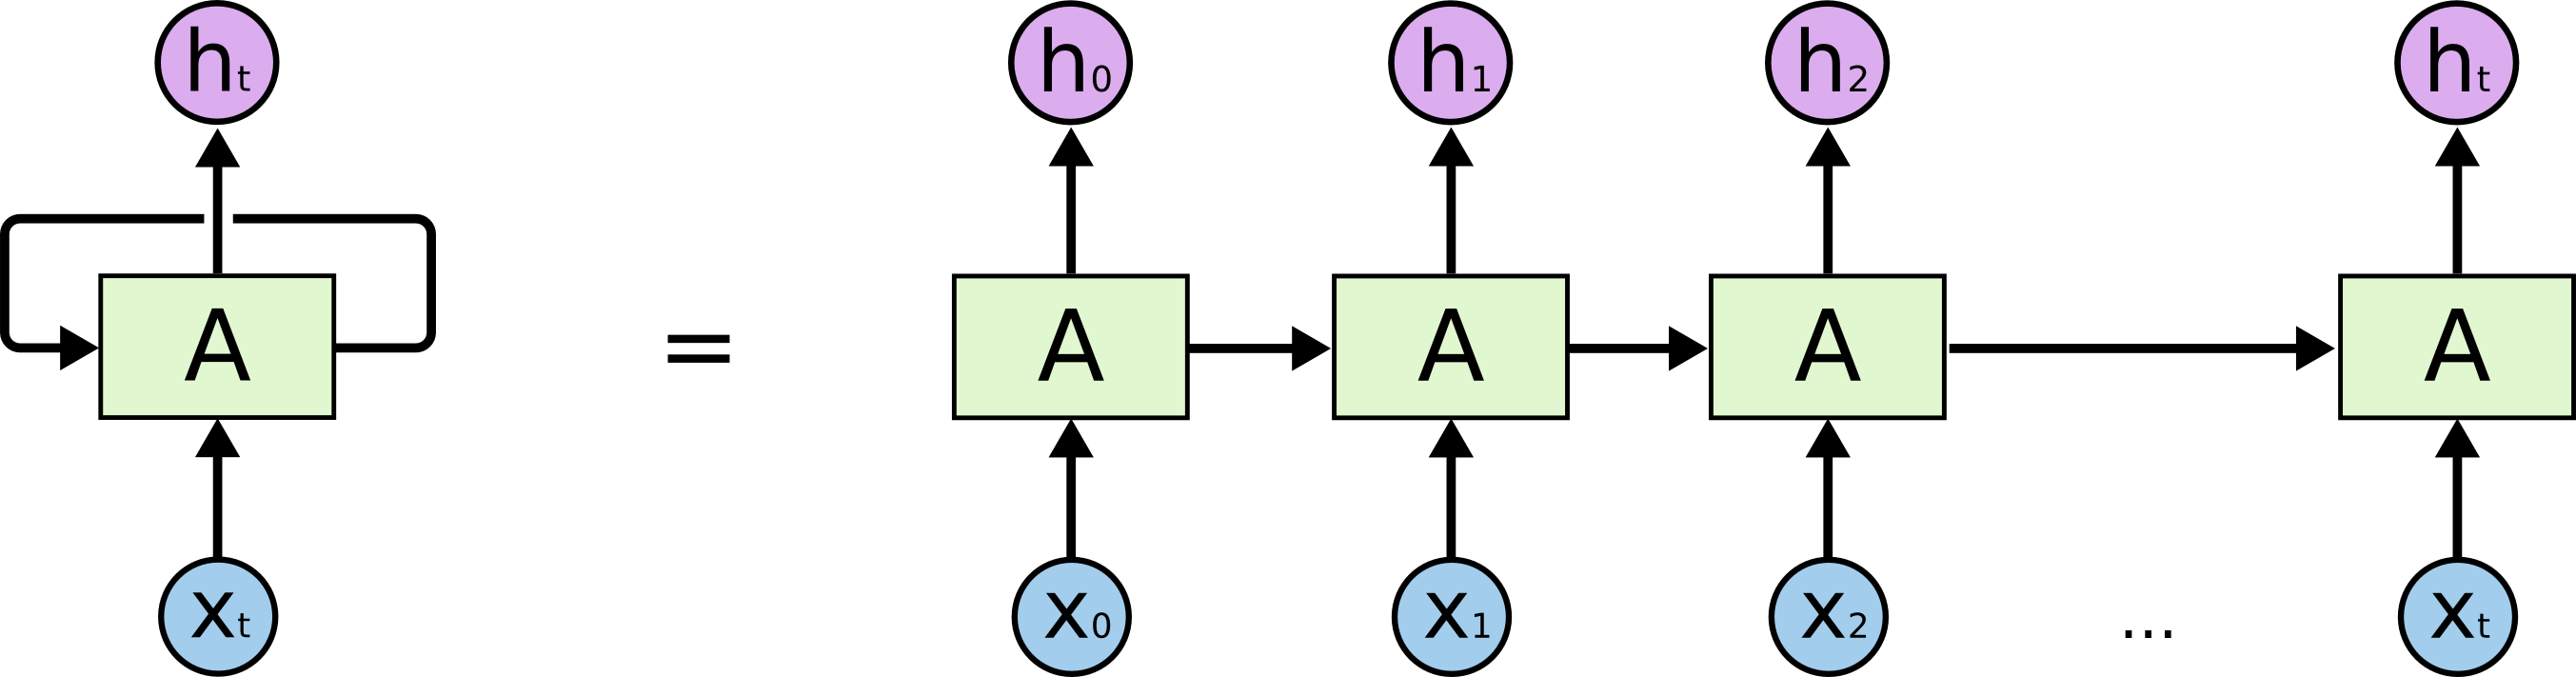
Understanding LSTM Networks -- colah's blog

Understanding LSTM Networks -- colah's blog

colah.github.io
A Recipe for Training Neural Networks

A Recipe for Training Neural Networks

karpathy.github.ioMusings of a Computer Scientist.
The Unreasonable Effectiveness of Recurrent Neural Networks

The Unreasonable Effectiveness of Recurrent Neural Networks

karpathy.github.ioMusings of a Computer Scientist.
Software 2.0

Software 2.0

karpathy.medium.comI sometimes see people refer to neural networks as just “another tool in your machine learning toolbox”. They have some pros and cons, they…
The Bitter Lesson

The Bitter Lesson

incompleteideas.net
AI Doesn’t Reduce Work—It Intensifies It

AI Doesn’t Reduce Work—It Intensifies It

simonwillison.netAruna Ranganathan and Xingqi Maggie Ye from Berkeley Haas School of Business report initial findings in the HBR from their April to December 2025 study of 200 employees at a …
Hallucination‐Free? Assessing the Reliability of Leading AI Legal Research Tools

Hallucination‐Free? Assessing the Reliability of Leading AI Legal Research Tools

dho.stanford.edu
Ten Principles of Good Design | Tony Gaeta

Ten Principles of Good Design | Tony Gaeta

tonygaeta.comDieter Rams' Ten Principles of Good Design.
power_of_proximity_nov2023.pdf

power_of_proximity_nov2023.pdf

pallais.scholars.harvard.edu
diegolnasc/kubernetes-best-practices: A cookbook with the best practices to working with kubernetes.

diegolnasc/kubernetes-best-practices: A cookbook with the best practices to working with kubernetes.

github.comA cookbook with the best practices to working with kubernetes. - diegolnasc/kubernetes-best-practices
Why Local-First Apps Haven’t Become Popular?

Why Local-First Apps Haven’t Become Popular?

marcobambini.substack.comOffline-first apps promise instant loading and privacy, but in practice, very few apps get offline support because getting sync right is surprisingly hard.
This is a Motherfucking App

This is a Motherfucking App

adnjoo.github.io
The Curse of Knowing How, or; Fixing Everything | Blog

The Curse of Knowing How, or; Fixing Everything | Blog

notashelf.devA reflection on control, burnout, and the strange weight of technical fluency.
DORA | Get Better at Getting Better

DORA | Get Better at Getting Better

dora.devDORA is a long running research program that seeks to understand the capabilities that drive software delivery and operations performance. DORA helps teams apply those capabilities, leading to better organizational performance.
Does Your Startup Really Need Complex Cloud Infrastructure? - Hadi Javeed's blog

Does Your Startup Really Need Complex Cloud Infrastructure? - Hadi Javeed's blog

hadijaveed.meNotes about startups, AI, health-care and overall engineering
HackTricks | HackTricks

HackTricks | HackTricks

book.hacktricks.xyz
Shape Up: Stop Running in Circles and Ship Work that Matters

Shape Up: Stop Running in Circles and Ship Work that Matters

basecamp.comShape Up will help you break free of “best practices” that aren’t really working, think deeper about the right problems, and start shipping meaningful projects your team can celebrate.
no hello

no hello

nohello.netplease don't say just hello in chat
awesome-engineering-team-management: 👔 How to transition from software development to engineering management

awesome-engineering-team-management: 👔 How to transition from software development to engineering management

github.com👔 How to transition from software development to engineering management - kdeldycke/awesome-engineering-team-management
Stirling-PDF: #1 Locally hosted web application that allows you to perform various operations on PDF files

Stirling-PDF: #1 Locally hosted web application that allows you to perform various operations on PDF files

github.com#1 Locally hosted web application that allows you to perform various operations on PDF files - Stirling-Tools/Stirling-PDF
How to build a startup pitch deck

How to build a startup pitch deck

openvc.appThis playbook is my home-made, battle-tested process to prepare the structure, content, and design of a typical early-stage startup pitch deck. These 2 hours of prep work will save you 10x more time down the road, I promise.
Agile Project Estimation Techniques | PMI

Agile Project Estimation Techniques | PMI

pmi.orgElaborate on two common techniques for agile estimation (planning poker and affinity grouping), and learn how the results provide input into forecasting.
Software Engineering - The Soft Parts

Software Engineering - The Soft Parts

addyosmani.comToday I will share some of the software engineering soft skills I have learned from my first 10 years on Google Chrome, where I am a Senior Staff Engineering...
Developer Productivity for Humans, Part 7: Software Quality | IEEE Journals & Magazine | IEEE Xplore

Developer Productivity for Humans, Part 7: Software Quality | IEEE Journals & Magazine | IEEE Xplore

ieeexplore.ieee.org
Code With Engineering Playbook

Code With Engineering Playbook

microsoft.github.io
Dario Amodei — The Urgency of Interpretability

Dario Amodei — The Urgency of Interpretability

darioamodei.com
AI models collapse when trained on recursively generated data - Nature

AI models collapse when trained on recursively generated data - Nature

nature.com Analysis shows that indiscriminately training generative artificial intelligence on real and generated content, usually done by scraping data from the Internet, can lead to a collapse in the ability of the models to generate diverse high-quality output.
The AI Revolution: The Road to Superintelligence

The AI Revolution: The Road to Superintelligence

waitbutwhy.comPart 1 of 2: "The Road to Superintelligence". Artificial Intelligence — the topic everyone in the world should be talking about.
On Chomsky and the Two Cultures of Statistical Learning

On Chomsky and the Two Cultures of Statistical Learning

norvig.com
I.—COMPUTING MACHINERY AND INTELLIGENCE

I.—COMPUTING MACHINERY AND INTELLIGENCE

academic.oup.comI propose to consider the question, ‘Can machines think?’ This should begin with definitions of the meaning of the terms ‘machine’ and ‘think’. The definit
Understanding LSTM Networks -- colah's blog

Understanding LSTM Networks -- colah's blog

colah.github.io
Software 2.0

Software 2.0

karpathy.medium.comI sometimes see people refer to neural networks as just “another tool in your machine learning toolbox”. They have some pros and cons, they…
Hallucination‐Free? Assessing the Reliability of Leading AI Legal Research Tools

Hallucination‐Free? Assessing the Reliability of Leading AI Legal Research Tools

dho.stanford.edu
diegolnasc/kubernetes-best-practices: A cookbook with the best practices to working with kubernetes.

diegolnasc/kubernetes-best-practices: A cookbook with the best practices to working with kubernetes.

github.comA cookbook with the best practices to working with kubernetes. - diegolnasc/kubernetes-best-practices
The Curse of Knowing How, or; Fixing Everything | Blog

The Curse of Knowing How, or; Fixing Everything | Blog

notashelf.devA reflection on control, burnout, and the strange weight of technical fluency.
HackTricks | HackTricks

HackTricks | HackTricks

book.hacktricks.xyz
awesome-engineering-team-management: 👔 How to transition from software development to engineering management

awesome-engineering-team-management: 👔 How to transition from software development to engineering management

github.com👔 How to transition from software development to engineering management - kdeldycke/awesome-engineering-team-management
Agile Project Estimation Techniques | PMI

Agile Project Estimation Techniques | PMI

pmi.orgElaborate on two common techniques for agile estimation (planning poker and affinity grouping), and learn how the results provide input into forecasting.
Code With Engineering Playbook

Code With Engineering Playbook

microsoft.github.io
Home - Keep The Future Human

Home - Keep The Future Human

keepthefuturehuman.aiHumanity is on the brink of developing artificial general intelligence that exceeds our own. It's time to close the gates on AGI and superintelligence... before we lose control of our future.
AIs have a favorite number, and it's not 42

AIs have a favorite number, and it's not 42

theregister.com: Ask a model to guess a number from 1 to 50 and it's likely to answer 27
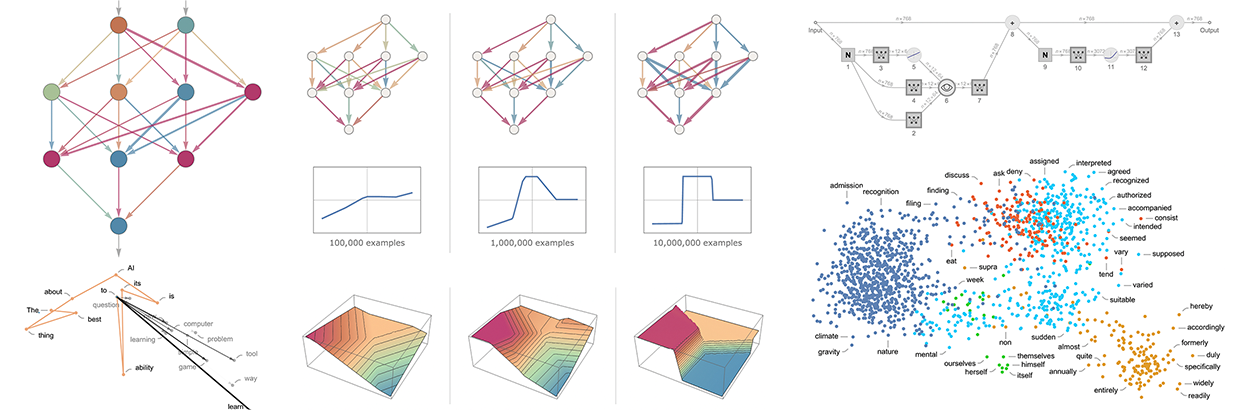
What Is ChatGPT Doing … and Why Does It Work?

What Is ChatGPT Doing … and Why Does It Work?

writings.stephenwolfram.comStephen Wolfram explores the broader picture of what's going on inside ChatGPT and why it produces meaningful text. Discusses models, training neural nets, embeddings, tokens, transformers, language syntax.
Man-Computer Symbiosis

Man-Computer Symbiosis

groups.csail.mit.edu
Neural networks and deep learning

Neural networks and deep learning

neuralnetworksanddeeplearning.com
A Recipe for Training Neural Networks

A Recipe for Training Neural Networks

karpathy.github.ioMusings of a Computer Scientist.
The Bitter Lesson

The Bitter Lesson

incompleteideas.net
Ten Principles of Good Design | Tony Gaeta

Ten Principles of Good Design | Tony Gaeta

tonygaeta.comDieter Rams' Ten Principles of Good Design.
Why Local-First Apps Haven’t Become Popular?

Why Local-First Apps Haven’t Become Popular?

marcobambini.substack.comOffline-first apps promise instant loading and privacy, but in practice, very few apps get offline support because getting sync right is surprisingly hard.
DORA | Get Better at Getting Better

DORA | Get Better at Getting Better

dora.devDORA is a long running research program that seeks to understand the capabilities that drive software delivery and operations performance. DORA helps teams apply those capabilities, leading to better organizational performance.
Shape Up: Stop Running in Circles and Ship Work that Matters

Shape Up: Stop Running in Circles and Ship Work that Matters

basecamp.comShape Up will help you break free of “best practices” that aren’t really working, think deeper about the right problems, and start shipping meaningful projects your team can celebrate.
Stirling-PDF: #1 Locally hosted web application that allows you to perform various operations on PDF files

Stirling-PDF: #1 Locally hosted web application that allows you to perform various operations on PDF files

github.com#1 Locally hosted web application that allows you to perform various operations on PDF files - Stirling-Tools/Stirling-PDF
Software Engineering - The Soft Parts

Software Engineering - The Soft Parts

addyosmani.comToday I will share some of the software engineering soft skills I have learned from my first 10 years on Google Chrome, where I am a Senior Staff Engineering...
Gradual Disempowerment

Gradual Disempowerment

gradual-disempowerment.ai
ChatGPT Is a Blurry JPEG of the Web

ChatGPT Is a Blurry JPEG of the Web

newyorker.comOpenAI’s chatbot offers paraphrases, whereas Google offers quotes. Which do we prefer?
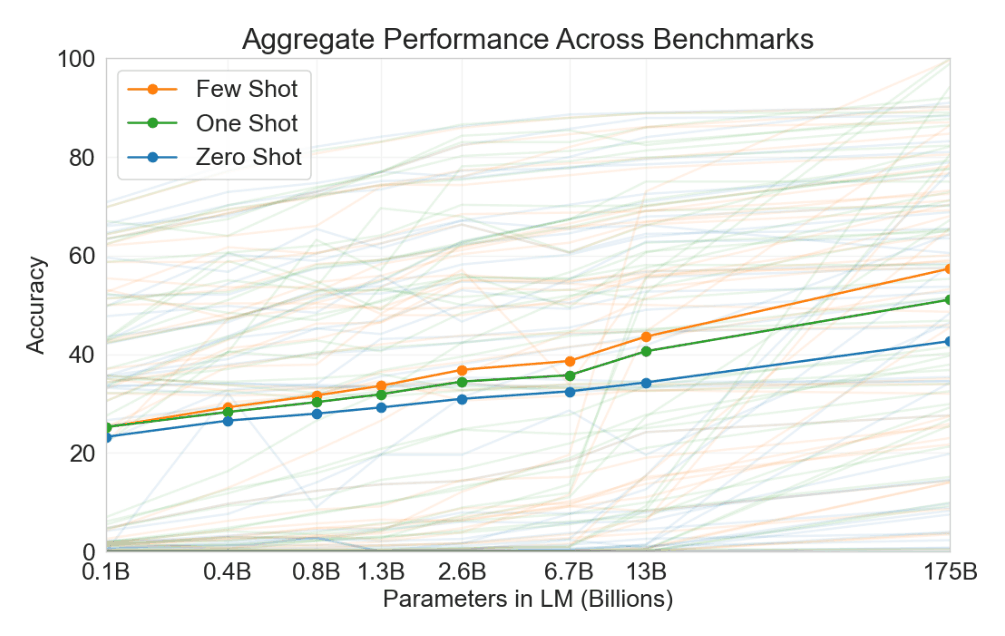
The Scaling Hypothesis

The Scaling Hypothesis

gwern.netOn GPT-3: meta-learning, scaling, implications, and deep theory. The scaling hypothesis: neural nets absorb data & compute, generalizing and becoming more Bayesian as problems get harder, manifesting new abilities even at trivial-by-global-standards-scale. The deep learning revolution has begun as foretold.
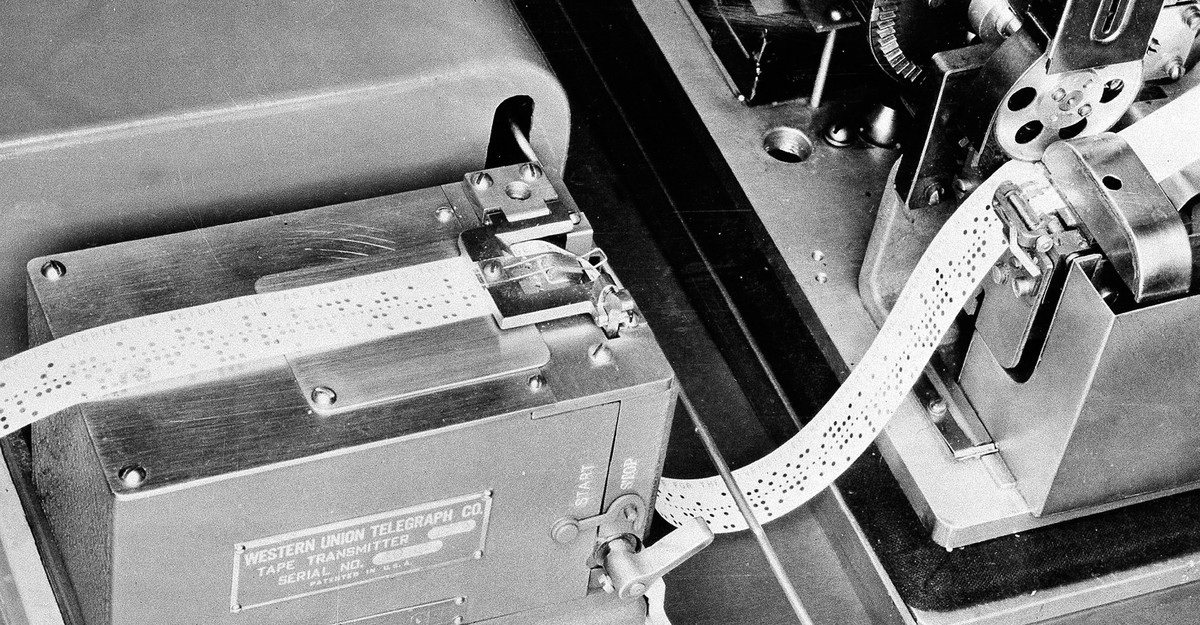
As We May Think

As We May Think

theatlantic.com“Consider a future device ... in which an individual stores all his books, records, and communications, and which is mechanized so that it may be consulted with exceeding speed and flexibility. It is an enlarged intimate supplement to his memory.”
The Illustrated Transformer

The Illustrated Transformer

jalammar.github.ioDiscussions: Hacker News (65 points, 4 comments), Reddit r/MachineLearning (29 points, 3 comments) Translations: Arabic, Chinese (Simplified) 1, Chinese (Simplified) 2, French 1, French 2, Italian, Japanese, Korean, Persian, Russian, Spanish 1, Spanish 2, Vietnamese Watch: MIT’s Deep Learning State of the Art lecture referencing this post Featured in courses at Stanford, Harvard, MIT, Princeton, CMU and others Update: This post has now become a book! Check out LLM-book.com which contains (Chapter 3) an updated and expanded version of this post speaking about the latest Transformer models and how they've evolved in the seven years since the original Transformer (like Multi-Query Attention and RoPE Positional embeddings). In the previous post, we looked at Attention – a ubiquitous method in modern deep learning models. Attention is a concept that helped improve the performance of neural machine translation applications. In this post, we will look at The Transformer – a model that uses attention to boost the speed with which these models can be trained. The Transformer outperforms the Google Neural Machine Translation model in specific tasks. The biggest benefit, however, comes from how The Transformer lends itself to parallelization. It is in fact Google Cloud’s recommendation to use The Transformer as a reference model to use their Cloud TPU offering. So let’s try to break the model apart and look at how it functions. The Transformer was proposed in the paper Attention is All You Need. A TensorFlow implementation of it is available as a part of the Tensor2Tensor package. Harvard’s NLP group created a guide annotating the paper with PyTorch implementation. In this post, we will attempt to oversimplify things a bit and introduce the concepts one by one to hopefully make it easier to understand to people without in-depth knowledge of the subject matter. 2025 Update: We’ve built a free short course that brings the contents of this post up-to-date with animations: A High-Level Look Let’s begin by looking at the model as a single black box. In a machine translation application, it would take a sentence in one language, and output its translation in another.
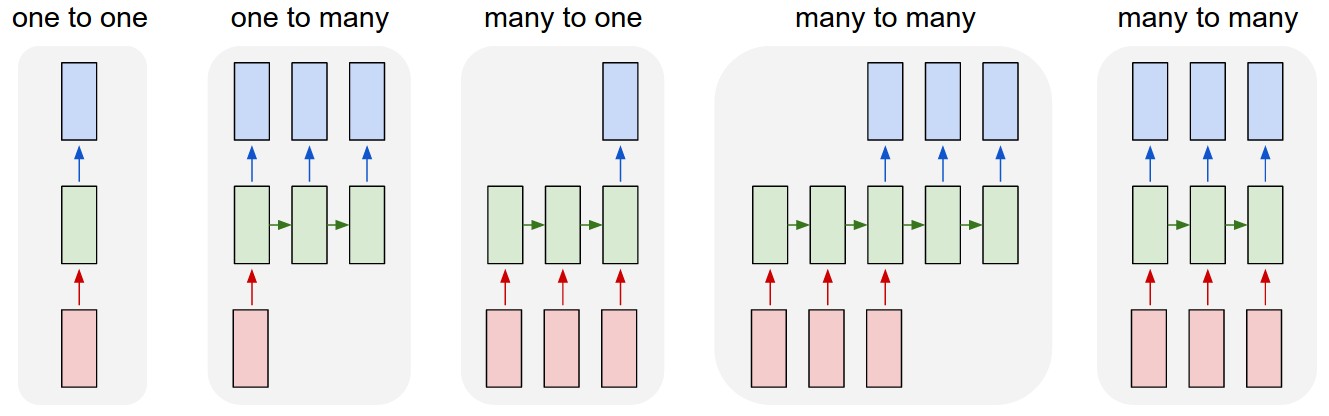
The Unreasonable Effectiveness of Recurrent Neural Networks

The Unreasonable Effectiveness of Recurrent Neural Networks

karpathy.github.ioMusings of a Computer Scientist.
AI Doesn’t Reduce Work—It Intensifies It

AI Doesn’t Reduce Work—It Intensifies It

simonwillison.netAruna Ranganathan and Xingqi Maggie Ye from Berkeley Haas School of Business report initial findings in the HBR from their April to December 2025 study of 200 employees at a …
power_of_proximity_nov2023.pdf

power_of_proximity_nov2023.pdf

pallais.scholars.harvard.edu
This is a Motherfucking App

This is a Motherfucking App

adnjoo.github.io
Does Your Startup Really Need Complex Cloud Infrastructure? - Hadi Javeed's blog

Does Your Startup Really Need Complex Cloud Infrastructure? - Hadi Javeed's blog

hadijaveed.meNotes about startups, AI, health-care and overall engineering
no hello

no hello

nohello.netplease don't say just hello in chat
How to build a startup pitch deck

How to build a startup pitch deck

openvc.appThis playbook is my home-made, battle-tested process to prepare the structure, content, and design of a typical early-stage startup pitch deck. These 2 hours of prep work will save you 10x more time down the road, I promise.
Developer Productivity for Humans, Part 7: Software Quality | IEEE Journals & Magazine | IEEE Xplore

Developer Productivity for Humans, Part 7: Software Quality | IEEE Journals & Magazine | IEEE Xplore

ieeexplore.ieee.org
That's all for now. Come back later for more.